import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import pandas_datareader as pdr
import yfinance as yfHerron Topic 1 - Log and Simple Returns, Portfolio Math, and Applications - Sec 04
FINA 6333 for Spring 2025
This notebook covers two topics:
- Log and simple returns
- Portfolio returns, plus two applications of portfolio returns
%precision 4
pd.options.display.float_format = '{:.4f}'.format
# %config InlineBackend.figure_format = 'retina'
Log and Simple Returns
We will typically use simple returns, calculated as \(r_{simple,t} = \frac{p_t + d_t - p_{t-1}}{p_{t-1}}\). This simple return is the return that investors earn on their investments. We can calculate simple returns from Yahoo Finance data with the .pct_change() method on the adjusted close column (i.e., Adj Close), which adjusts for dividends and splits. The adjusted close column is a reverse-engineered close price (i.e., end-of-trading-day price) that incorporates dividends and splits, making simple return calculations easy.
However, we may see log returns elsewhere, which are the (natural) log of one plus simple returns: \(r_{log,t} = \log(1 + r_{simple,t})\). Therefore, we calculate log returns as either the log of one plus simple returns or the difference of the logs of the adjusted close column. Log returns are also known as continuously-compounded returns.
This section explains the differences between simple and log returns and where each is appropriate.
Simple and Log Returns are Similar for Small Returns
\(x \approx \log(1 + x)\) for small values of \(x\), so simple returns and log returns are similar for small returns. Returns are typically small at daily and monthly horizons, so the difference between simple and log returns is small at daily and monthly horizons. The following figure shows that \(r_{simple,t} \approx r_{log,t}\) for small values of \(r\).
simpler = np.linspace(-0.75, 0.75, 100)
logr = np.log1p(simpler)
plt.plot(simpler, logr)
plt.plot([-1, 1], [-1, 1])
plt.xlabel('Simple Return')
plt.ylabel('Log Return')
plt.title('Log Versus Simple Returns')
plt.legend(['Actual Relation', 'Relation If Log = Simple'])
plt.show()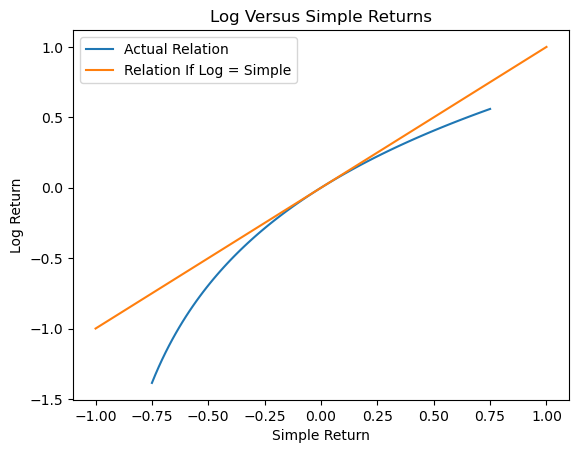
Simple Return Advantage: Portfolio Calculations
For a portfolio of \(N\) assets with portfolio weights \(w_i\), the portfolio return \(r_p\) is the weighted average of the returns of its assets: \(r_p = \sum_{i=1}^N w_i r_{i}\). For example, for an equal-weighted portfolio with two stocks, \(r_p = 0.5 r_1 + 0.5 r_2 = \frac{r_1 + r_2}{2}\). Therefore, we cannot calculate portfolio returns with log returns because the sum of logs is the log of products. That is \(\log(1+r_i) + \log(1+r_j) = \log((1+r_i) \times (1+r_j))\), which is not what we want to measure! We cannot perform portfolio calculations with log returns!
Log Return Advantage: Log Returns are Additive
We compound simple returns with multiplication, but we compound log returns with addition. This additive property of log returns makes code simple, computations fast, and proofs easy when we must compound returns.
We compound returns from \(t=0\) to \(t=T\) as follows: \[1 + r_{0, T} = (1 + r_1) \times (1 + r_2) \times \dots \times (1 + r_T)\] Next, we take the log of both sides of the previous equation and use the property that the log of products is the sum of logs: \[\log(1 + r_{0, T}) = \log((1 + r_1) \times (1 + r_2) \times \dots \times (1 + r_T)) = \log(1 + r_1) + \log(1 + r_2) + \dots + \log(1 + r_T) = \sum_{t=1}^T \log(1 + r_t)\] Next, we exponentiate both sides of the previous equation: \[e^{\log(1 + r_{0, T})} = e^{\sum_{t=0}^T \log(1 + r_t)}\] Next, we use the property that \(e^{\log(x)} = x\) to simplify the previous equation: \[1 + r_{0,T} = e^{\sum_{t=0}^T \log(1 + r_t)}\] Finally, we subtract 1 from both sides: \[r_{0 ,T} = e^{\sum_{t=0}^T \log(1 + r_t)} - 1\] So, the return \(r_{0,T}\) from \(t=0\) to \(t=T\) is the exponentiated sum of log returns. The pandas developers assume users understand the math above and focus on optimizing sums!
np.random.seed(42)
df = pd.DataFrame(data={'r': np.exp(np.random.randn(10_000)) - 1})

df.describe()| r | |
|---|---|
| count | 10000.0000 |
| mean | 0.6529 |
| std | 2.1918 |
| min | -0.9802 |
| 25% | -0.4896 |
| 50% | -0.0026 |
| 75% | 0.9564 |
| max | 49.7158 |
We can time the calculation of 10-observation rolling returns. We use .apply() for the simple return version because .rolling() does not have a product method. We find that .rolling() is slower with .apply() than with .sum() by a factor of about 1,000. We will learn about .rolling() and .apply() in a few weeks, but they provide the best example of when to use log returns.
%%timeit
df['r10_via_prod'] = (
    df['r']
    .add(1)
    .rolling(10)
    .apply(lambda x: x.prod())
    .sub(1)
)
208 ms ± 40.1 ms per loop (mean ± std. dev. of 7 runs, 1 loop each)%%timeit
df['r10_via_sum'] = (
df['r']
.add(1)
.pipe(np.log)
.rolling(10)
.sum()
.pipe(np.exp)
.sub(1)
)1.49 ms ± 443 μs per loop (mean ± std. dev. of 7 runs, 1,000 loops each)df.head(15)| r | r10_via_prod | r10_via_sum | |
|---|---|---|---|
| 0 | 0.6433 | NaN | NaN |
| 1 | -0.1291 | NaN | NaN |
| 2 | 0.9111 | NaN | NaN |
| 3 | 3.5861 | NaN | NaN |
| 4 | -0.2088 | NaN | NaN |
| 5 | -0.2087 | NaN | NaN |
| 6 | 3.8511 | NaN | NaN |
| 7 | 1.1542 | NaN | NaN |
| 8 | -0.3747 | NaN | NaN |
| 9 | 0.7204 | 87.2886 | 87.2886 |
| 10 | -0.3709 | 32.8006 | 32.8006 |
| 11 | -0.3723 | 23.3617 | 23.3617 |
| 12 | 0.2737 | 15.2369 | 15.2369 |
| 13 | -0.8524 | -0.4774 | -0.4774 |
| 14 | -0.8218 | -0.8823 | -0.8823 |
np.allclose(df['r10_via_prod'], df['r10_via_sum'], equal_nan=True)TrueThese two approaches calculate the same return series, but the simple-return approach using .prod() is about 1,000 times slower than the log-return approach using .sum()! We can use log returns to calculate total returns very quickly!
Portfolio Math
Portfolio return \(r_{p}\) is the weighted average of its asset returns, so \(r_{p} = \sum_{i=1}^N w_i r_{i}\). Here \(N\) is the number of assets, \(w_i\) is the weight on asset \(i\), and \(\sum_{i=1}^N w_i = 1\).
The 1/N Portfolio
The \(\frac{1}{N}\) portfolio equally weights portfolio assets, so \(w_1 = w_2 = \dots = w_N = \frac{1}{N}\). If \(w_i = \frac{1}{N}\), then \(r_{p} = \sum_{i=1}^N \frac{1}{N} r_{i} = \frac{\sum_{i=1}^N r_i}{N} = \bar{r}\). Therefore, we can use .mean(axis=1) to calculate \(\frac{1}{N}\) portfolio returns!
df2 = yf.download(tickers='AAPL AMZN GOOG MSFT NVDA TSLA', auto_adjust=False, progress=False).iloc[:-1]
returns2 = df2['Adj Close'].pct_change().dropna()

returns2.describe()| Ticker | AAPL | AMZN | GOOG | MSFT | NVDA | TSLA |
|---|---|---|---|---|---|---|
| count | 3689.0000 | 3689.0000 | 3689.0000 | 3689.0000 | 3689.0000 | 3689.0000 |
| mean | 0.0011 | 0.0012 | 0.0009 | 0.0010 | 0.0021 | 0.0021 |
| std | 0.0175 | 0.0205 | 0.0173 | 0.0161 | 0.0288 | 0.0362 |
| min | -0.1286 | -0.1405 | -0.1110 | -0.1474 | -0.1876 | -0.2106 |
| 25% | -0.0074 | -0.0089 | -0.0071 | -0.0070 | -0.0122 | -0.0164 |
| 50% | 0.0010 | 0.0010 | 0.0009 | 0.0007 | 0.0017 | 0.0012 |
| 75% | 0.0102 | 0.0119 | 0.0093 | 0.0093 | 0.0161 | 0.0194 |
| max | 0.1198 | 0.1575 | 0.1605 | 0.1422 | 0.2981 | 0.2440 |
returns2.mean() # implied axis=0Ticker
AAPL 0.0011
AMZN 0.0012
GOOG 0.0009
MSFT 0.0010
NVDA 0.0021
TSLA 0.0021
dtype: float64rp2_via_mean = returns2.mean(axis=1)
rp2_via_meanDate
2010-06-30 -0.0123
2010-07-01 -0.0107
2010-07-02 -0.0271
2010-07-06 -0.0223
2010-07-07 0.0254
...
2025-02-21 -0.0272
2025-02-24 -0.0127
2025-02-25 -0.0247
2025-02-26 -0.0055
2025-02-27 -0.0330
Length: 3689, dtype: float64Note that when we apply the same portfolio weights every period, we rebalance at the same frequency as the returns data. If we have daily data, rebalance daily. If we have monthly data, we rebalance monthly, and so on.
A More General Solution
If we combine portfolio weights into vector \(w\) and the time series of asset returns into matrix \(\mathbf{R}\), then we can calculate the time series of portfolio returns as \(r_p = w^T \mathbf{R}\). The pandas version of this calculation is R.dot(w), where R is a data frame of asset returns and w is a series or an array of portfolio weights. We can use this approach to calculate \(\frac{1}{N}\) portfolio returns, too.
returns2.shape(3689, 6)weights2 = np.ones(returns2.shape[1]) / returns2.shape[1]
weights2array([0.1667, 0.1667, 0.1667, 0.1667, 0.1667, 0.1667])rp2_via_dot = returns2.dot(weights2)
rp2_via_dotDate
2010-06-30 -0.0123
2010-07-01 -0.0107
2010-07-02 -0.0271
2010-07-06 -0.0223
2010-07-07 0.0254
...
2025-02-21 -0.0272
2025-02-24 -0.0127
2025-02-25 -0.0247
2025-02-26 -0.0055
2025-02-27 -0.0330
Length: 3689, dtype: float64Both approaches give the same answer!
np.allclose(rp2_via_mean, rp2_via_dot, equal_nan=True)TruePortfolio Math Application 1: All stocks half the time or half stocks all the time?
Are you better off investing:
- 100% in stocks 50% of the time and the riskless asset the other 50% of the time or
- 50% in stocks and 50% in the riskless asset 100% of the time?
Here is a roadmap for convincing yourself with data!
Please see Kritzman (2000, chap. 5) for a more detailed solution!
Download annual market and risk-free asset returns from Kenneth French’s data library
pdr.famafrench.get_available_datasets()[:5]['F-F_Research_Data_Factors',
'F-F_Research_Data_Factors_weekly',
'F-F_Research_Data_Factors_daily',
'F-F_Research_Data_5_Factors_2x3',
'F-F_Research_Data_5_Factors_2x3_daily']ff = pdr.DataReader(
name='F-F_Research_Data_Factors',
data_source='famafrench',
start='1900'
)C:\Users\r.herron\AppData\Local\Temp\ipykernel_24988\304025689.py:1: FutureWarning: The argument 'date_parser' is deprecated and will be removed in a future version. Please use 'date_format' instead, or read your data in as 'object' dtype and then call 'to_datetime'.
ff = pdr.DataReader(
C:\Users\r.herron\AppData\Local\Temp\ipykernel_24988\304025689.py:1: FutureWarning: The argument 'date_parser' is deprecated and will be removed in a future version. Please use 'date_format' instead, or read your data in as 'object' dtype and then call 'to_datetime'.
ff = pdr.DataReader(print(ff['DESCR'])F-F Research Data Factors
-------------------------
This file was created by CMPT_ME_BEME_RETS using the 202412 CRSP database. The 1-month TBill rate data until 202405 are from Ibbotson Associates. Starting from 202406, the 1-month TBill rate is from ICE BofA US 1-Month Treasury Bill Index. Copyright 2024 Eugene F. Fama and Kenneth R. French
0 : (1182 rows x 4 cols)
1 : Annual Factors: January-December (98 rows x 4 cols)Convert these factors to decimal returns and calculate the market return series
df3 = ff[1].div(100)df3['Mkt'] = df3['Mkt-RF'] + df3['RF']Add a portfolio return series that is half stocks all the time
You might call this portfolio return series Balanced
df3['Balanced'] = df3[['Mkt', 'RF']].mean(axis=1)Add a portfolio return series that switches between stocks and bills every year with stocks in odd years
You might call this portfolio return series Switching Stocks Odd
df3['Switching Stocks Odd'] = np.where(df3.index.year % 2 == 1, df3['Mkt'], df3['RF'])Add a portfolio return series that switches between stocks and bills every year with stocks in even years
You might call this portfolio return series Switching Stocks Even
df3['Switching Stocks Even'] = np.where(df3.index.year % 2 == 0, df3['Mkt'], df3['RF'])df3.head()| Mkt-RF | SMB | HML | RF | Mkt | Balanced | Switching Stocks Odd | Switching Stocks Even | |
|---|---|---|---|---|---|---|---|---|
| Date | ||||||||
| 1927 | 0.2947 | -0.0204 | -0.0454 | 0.0312 | 0.3259 | 0.1785 | 0.3259 | 0.0312 |
| 1928 | 0.3539 | 0.0451 | -0.0617 | 0.0356 | 0.3895 | 0.2126 | 0.0356 | 0.3895 |
| 1929 | -0.1954 | -0.3070 | 0.1167 | 0.0475 | -0.1479 | -0.0502 | -0.1479 | 0.0475 |
| 1930 | -0.3123 | -0.0517 | -0.1154 | 0.0241 | -0.2882 | -0.1321 | 0.0241 | -0.2882 |
| 1931 | -0.4511 | 0.0370 | -0.1395 | 0.0107 | -0.4404 | -0.2149 | -0.4404 | 0.0107 |
Plot the cumulative returns on a $1 investment and calculate the summary statistics for the Balanced and Switching series
Use the .describe() method to calculate summary statistics.
portfolios = ['Balanced', 'Switching Stocks Odd', 'Switching Stocks Even']import matplotlib.ticker as ticker(
df3[portfolios]
.add(1)
.cumprod()
.plot()
)
plt.yscale('log')
plt.ylabel('Value of $1 Investment')
plt.title(f'Value of $1 in Investment in Three Strategies\nfrom {df3.index.year[0]} through {df3.index.year[-1]}')
plt.show()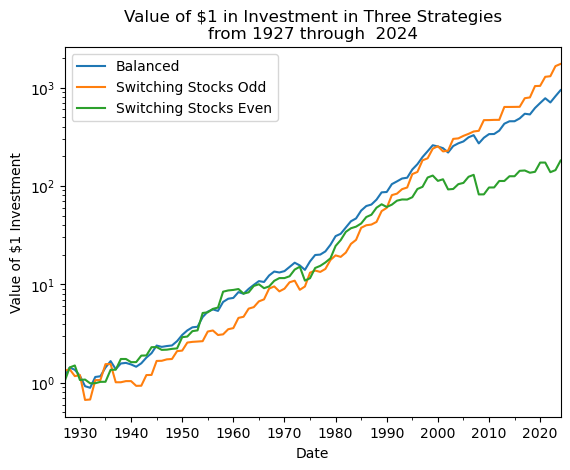
Which strategy do you prefer?
Why? How sure are you?
The Switching Stocks Odd strategy seems best in this example! However, this apparent superiority is largely a matter of luck, specifically this combination of the sample period and starting year. In this sample, the number of even and odd years is equal, but the market happened to perform better in odd years. This outcome is entirely driven by this particular historical sequence.
To draw broader conclusions, we must break free from the “luck of the draw” tied to this single realization of history. Below, we will explore two approaches to determine which strategy is better:
- Theory: We will analyze the expected returns and variances mathematically to assess the underlying return-risk tradeoff for each strategy.
- Simulation: To rely on data instead of theory, we will simulate thousands of alternative historical sequences.
By shuffling the 98 years of market data repeatedly, we can generate 10,000 random samples and evaluate the performance of each strategy across these simulations.
This approach allows us to:
- Confirm that both strategies have the same arithmetic average return.
- Show that the balanced strategy consistently delivers a better return-risk tradeoff (Sharpe ratio) when evaluated across many possible outcomes.
We will do the simulation first.
Use the simulate() function to simulate 10,000 different outcomes for the U.S. market
simulate() calculates one Switching return series because the randomization also randomizes the odd-year and even-year choice.
df3[['Mkt', 'RF']].sample(frac=1, ignore_index=True, random_state=42).head()| Mkt | RF | |
|---|---|---|
| 0 | 0.2886 | 0.0837 |
| 1 | 0.2870 | 0.0421 |
| 2 | 0.2361 | 0.0004 |
| 3 | 0.3871 | 0.0033 |
| 4 | -0.3674 | 0.0160 |
def simulate(df, cols=['Mkt', 'RF'], n_iter=10_000):
    """
    Simulates resampling of the given DataFrame columns and computes bal;anced and switching portfolio returns.

    Parameters:
    df (pd.DataFrame): The input DataFrame.
    cols (list): List of column names to sample.
    n_iter (int): Number of iterations for simulation.

    Returns:
    pd.DataFrame: A concatenated DataFrame with simulation results.
    """
    return pd.concat(
        objs=[(
            df[cols]
            .sample(frac=1, ignore_index=True, random_state=i)
            .assign(
                Balanced=lambda x: x[cols].mean(axis=1),
                Switching=lambda x: np.where(x.index % 2 == 0, x[cols[0]], x[cols[1]])
            )
        ) for i in range(n_iter)],
        keys=range(n_iter),
        names=['Simulation', 'Year']
    )
df4 = simulate(df3)df4.head()| Mkt | RF | Balanced | Switching | ||
|---|---|---|---|---|---|
| Simulation | Year | ||||
| 0 | 0 | 0.0077 | 0.0182 | 0.0129 | 0.0077 |
| 1 | 0.1633 | 0.0006 | 0.0819 | 0.0006 | |
| 2 | -0.1479 | 0.0475 | -0.0502 | -0.1479 | |
| 3 | 0.2120 | 0.1054 | 0.1587 | 0.1054 | |
| 4 | 0.3682 | 0.0560 | 0.2121 | 0.3682 |
Calculate the summary statistics for these new Balanced and Switching series
df4[['Balanced', 'Switching']].agg(['mean', 'std'])| Balanced | Switching | |
|---|---|---|
| mean | 0.0772 | 0.0774 |
| std | 0.1001 | 0.1487 |
We see that Balanced and Switching have the same mean return, but Balanced has much lower volatility than Switching! A risk-averse investor prefers Balanced because it has a higher return/risk ratio than Switching. We can quantify this ratio as the Sharpe ratio, which is the mean excess return divided by the volatility of excess returns: \(S_i = \frac{\overline{r_i - r_f}}{\sigma(r_i - r_f)}\). We can calcualte excess returns and Sharpe ratios in one code snippet.
(
    df4
    [['Balanced', 'Switching']]
    .sub(df4['RF'], axis=0)
    .agg(lambda x: x.mean() / x.std())
    .to_frame('Sharpe ratio')
)| Sharpe ratio | |
|---|---|
| Balanced | 0.4368 |
| Switching | 0.2961 |
We have to do a little more work if we want to combine mean and volatility of raw returns with the Sharpe ratio of excess returns.
pd.concat(
    objs=[
        df4[['Balanced', 'Switching']].agg(['mean', 'std']).transpose(),
        df4[['Balanced', 'Switching']].sub(df4['RF'], axis=0).agg(lambda x: x.mean() / x.std()).to_frame('Sharpe ratio')
    ],
    axis=1
)| mean | std | Sharpe ratio | |
|---|---|---|---|
| Balanced | 0.0772 | 0.1001 | 0.4368 |
| Switching | 0.0774 | 0.1487 | 0.2961 |
Which strategy do you prefer?
Why? How sure are you?
We prefer Balanced because it has a Sharpe ratio about 50% greater than Switching! We can see this in the data above, and here is the theory.
For Balanced, \(\sigma_p^2 = w_m^2 \sigma_m^2 + w_f^2 \sigma_f^2 + 2 w_m w_f \sigma_m \sigma_f \rho_{m,f}\). Because \(\sigma_f^2 \approx 0\) and \(\rho_{m,f} \approx 0\), \(\sigma_p^2 \approx w_m^2 \sigma_m^2\). Therefore, for Balanced \(\sigma_p \approx w_m \sigma_m = \frac{1}{2} \sigma_m\). We see this in the data!
0.5 * df3['Mkt'].std()0.0998df4['Balanced'].std()0.1001For Switching, \(\sigma_p^2 = w_m \sigma_m^2 + w_f \sigma_f^2 + w_m w_f (\mu_m - \mu_f)^2\). We have a different formula because Switching is diversified over time instead at a point in time! Because \(\sigma_f^2 \approx 0\) and \((\mu_m - \mu_f)^2 \approx 0\), \(\sigma_p^2 \approx w_m \sigma_m^2\). Therefore, for Balanced \(\sigma_p \approx \sqrt{w_m} \sigma_m = \sqrt{\frac{1}{2}} \sigma_m\). We see this in the data!
np.sqrt(0.5) * df3['Mkt'].std()0.1411df4['Switching'].std()0.1487The \((\mu_m - \mu_f)^2\) is close to zero but not exactly zero. We can get even closed to the observed Switching portfolio volatility if we consider this term!
np.sqrt(0.5 * df3['Mkt'].var() + 0.5 * 0.5 * (df3['Mkt'].mean() - df3['RF'].mean())**2)0.1478Here are two after-class additions to this question.
Can we add a progress bar?
Yes! We have to rewrite the simulate() function and replace the list comprehension with a for loop. However, this addition requires the tqdm package. To avoid any conflicts, I will not install this package and provide the code as markdown instead of executable code.
from tqdm import tqdm

def simulate(df, cols=['Mkt', 'RF'], n_iter=10_000):
    """
    Simulates resampling of the given DataFrame columns and computes balanced
    and switching portfolio returns.

    Parameters:
    -----------
    df : pd.DataFrame
        The input DataFrame.
    cols : list
        List of column names to sample.
    n_iter : int
        Number of iterations for simulation.

    Returns:
    --------
    pd.DataFrame
        A concatenated DataFrame with simulation results.
    """
    all_resamples = []

    # Use tqdm to visualize progress
    for i in tqdm(range(n_iter), desc="Simulating"):
        # Random re-sampling
        resampled = (
            df[cols]
            .sample(frac=1, ignore_index=True, random_state=i)
            .assign(
                Balanced=lambda x: x[cols].mean(axis=1),
                Switching=lambda x: np.where(
                    x.index % 2 == 0,
                    x[cols[0]],
                    x[cols[1]]
                )
            )
        )
        all_resamples.append(resampled)

    # Concatenate final results
    return pd.concat(all_resamples, keys=range(n_iter), names=['Simulation', 'Year'])
Ideally, we calculate the mean and volatility of each simulation, then take the average
We can do this easily with either .groupby() of .pivot_table()!
(
    df4
    .groupby(level='Simulation')
    [['Balanced', 'Switching']]
    .agg(['mean', 'std'])
    .mean()
    .unstack()
)| mean | std | |
|---|---|---|
| Balanced | 0.0772 | 0.1006 |
| Switching | 0.0774 | 0.1488 |
These statistics are similar, but not identical!
Portfolio Math Application 2: What are the benefits of diversification?
Use random portfolios of S&P 100 stocks of various portfolio sizes to show that portfolio volatility falls quickly, then slowly, then not at all as we increase portfolio size.
Download daily data for the stocks in the S&P 100
Wikipedia provides tickers for the stocks in the S&P 100. Use a list comprehension to replace . in tickers with - for compatability with Yahoo! Finance.
wiki = pd.read_html('https://en.wikipedia.org/wiki/S%26P_100')
tickers = [i.replace('.', '-') for i in wiki[2]['Symbol']]
data = yf.download(tickers=tickers, auto_adjust=False, progress=False).iloc[:-1]
Calculate the past five years of dailty returns for these stocks
returns = (
    data
    ['Adj Close']
    .dropna(axis=1, how='all')
    .pct_change()
    .iloc[-5*252:]
)
Calculate the volatilies of 20 equal-weighted random portfolios of various portfolio sizes
Random portfolios should have portfolio sizes of 1, 2, 4, 6, 8, 10, 20, 30, 40, or 50 stocks each.
You can combine the .sample(n=?, axis=1, random_state=?), .mean(axis=1), and .std() to calculate the volatilities of equal-weighted portfolios. You can collect these volatilies in a list of lists built with two for loops or list comprehensions. Replace the ?s in .sample() with loop counters. The inner loop will calculate a portfolio volatilty for each portfolio size, and the outer loop will collect 20 versions of each portfolio. Using the outer loop counter for random_state= makes your analysis repeatable!
portfolio_size = [1, 2, 4, 6, 8, 10, 20, 30, 40, 50]
portfolio_number = 20

list_of_volatilities = []
for i in range(portfolio_number):
list_of_volatilities.append([returns.sample(n=j, axis=1, random_state=i).mean(axis=1).std() for j in portfolio_size])list_of_volatilities[0][0.0153,
0.0127,
0.0121,
0.0118,
0.0134,
0.0129,
0.0128,
0.0129,
0.0129,
0.0129]Combine this list of lists into a data frame
volatilities = (
    pd.DataFrame(
        data=list_of_volatilities,
        index=range(1, 1+portfolio_number),
        columns=portfolio_size
    )
    .rename_axis(index='Portfolio Number', columns='Portfolio Size')
)volatilities| Portfolio Size | 1 | 2 | 4 | 6 | 8 | 10 | 20 | 30 | 40 | 50 |
|---|---|---|---|---|---|---|---|---|---|---|
| Portfolio Number | ||||||||||
| 1 | 0.0153 | 0.0127 | 0.0121 | 0.0118 | 0.0134 | 0.0129 | 0.0128 | 0.0129 | 0.0129 | 0.0129 |
| 2 | 0.0193 | 0.0144 | 0.0127 | 0.0145 | 0.0144 | 0.0145 | 0.0137 | 0.0136 | 0.0136 | 0.0133 |
| 3 | 0.0160 | 0.0165 | 0.0161 | 0.0151 | 0.0142 | 0.0144 | 0.0132 | 0.0134 | 0.0133 | 0.0134 |
| 4 | 0.0193 | 0.0177 | 0.0172 | 0.0171 | 0.0157 | 0.0156 | 0.0141 | 0.0141 | 0.0142 | 0.0139 |
| 5 | 0.0205 | 0.0199 | 0.0151 | 0.0164 | 0.0141 | 0.0133 | 0.0127 | 0.0131 | 0.0128 | 0.0131 |
| 6 | 0.0182 | 0.0157 | 0.0123 | 0.0136 | 0.0136 | 0.0139 | 0.0137 | 0.0143 | 0.0137 | 0.0136 |
| 7 | 0.0199 | 0.0174 | 0.0171 | 0.0160 | 0.0148 | 0.0142 | 0.0124 | 0.0133 | 0.0130 | 0.0128 |
| 8 | 0.0280 | 0.0178 | 0.0142 | 0.0149 | 0.0144 | 0.0131 | 0.0141 | 0.0138 | 0.0134 | 0.0134 |
| 9 | 0.0150 | 0.0136 | 0.0115 | 0.0116 | 0.0117 | 0.0119 | 0.0131 | 0.0132 | 0.0131 | 0.0133 |
| 10 | 0.0141 | 0.0171 | 0.0164 | 0.0150 | 0.0146 | 0.0147 | 0.0138 | 0.0131 | 0.0128 | 0.0126 |
| 11 | 0.0285 | 0.0210 | 0.0185 | 0.0170 | 0.0163 | 0.0167 | 0.0143 | 0.0142 | 0.0136 | 0.0137 |
| 12 | 0.0172 | 0.0193 | 0.0148 | 0.0154 | 0.0137 | 0.0140 | 0.0137 | 0.0133 | 0.0125 | 0.0128 |
| 13 | 0.0150 | 0.0131 | 0.0124 | 0.0126 | 0.0142 | 0.0134 | 0.0138 | 0.0133 | 0.0131 | 0.0135 |
| 14 | 0.0280 | 0.0198 | 0.0160 | 0.0147 | 0.0147 | 0.0137 | 0.0137 | 0.0131 | 0.0133 | 0.0134 |
| 15 | 0.0282 | 0.0197 | 0.0152 | 0.0142 | 0.0148 | 0.0142 | 0.0143 | 0.0140 | 0.0133 | 0.0134 |
| 16 | 0.0188 | 0.0150 | 0.0148 | 0.0136 | 0.0138 | 0.0140 | 0.0138 | 0.0141 | 0.0137 | 0.0136 |
| 17 | 0.0165 | 0.0132 | 0.0149 | 0.0141 | 0.0133 | 0.0128 | 0.0130 | 0.0133 | 0.0133 | 0.0131 |
| 18 | 0.0213 | 0.0198 | 0.0177 | 0.0166 | 0.0161 | 0.0156 | 0.0145 | 0.0142 | 0.0135 | 0.0139 |
| 19 | 0.0132 | 0.0136 | 0.0143 | 0.0140 | 0.0150 | 0.0145 | 0.0139 | 0.0134 | 0.0131 | 0.0127 |
| 20 | 0.0205 | 0.0209 | 0.0169 | 0.0154 | 0.0151 | 0.0143 | 0.0137 | 0.0134 | 0.0132 | 0.0132 |
Calculate the mean volatility for each portfolio size and replicate the plot above
volatilities.mul(100 * np.sqrt(252)).mean().plot()
plt.xlabel('Portfolio Size')
plt.ylabel('Mean of Annualized Volatility (%)')
plt.title('Diminishing Returns to Diversification (Elton and Gruber, 1977)')
plt.show()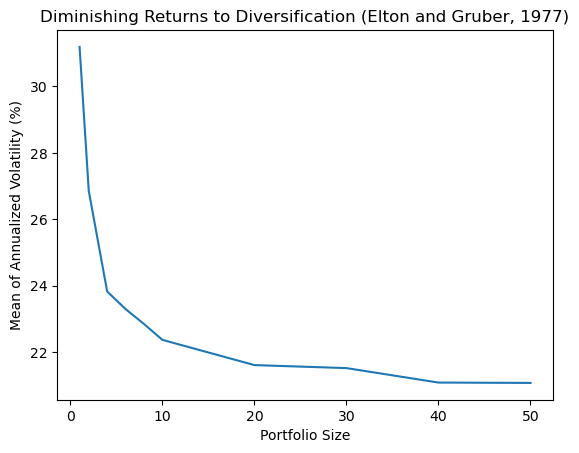
References
Kritzman, Mark P. 2000. Puzzles of Finance: Six Practical Problems and Their Remarkable Solutions. John Wiley & Sons.